
Omni-InteractScope Benchmark Exposes Timing and Sustained Intervention Failures in Omnimodal LLMs
What happened
Researchers from Alibaba Group and The Hong Kong Polytechnic University introduced Omni-InteractScope, a benchmark testing 12 omnimodal language models across 1,479 streaming audiovisual cases that revealed significant failures in proactive assistance.
The Context
* Proactive support falls short: Evaluated models managed at best a 23.0% recall rate when tasked with delivering query-free reminders during ongoing audiovisual streams. * Complex workflows collapse: Nine of the 12 tested models failed to complete a single one of the 26 multi-step guidance sequences evaluated in the benchmark. * Timing remains the hurdle: The benchmark assessed 1,790 temporal targets across eight task groups, showing that current architectures struggle to balance event grounding with real-time tool execution.
The Number
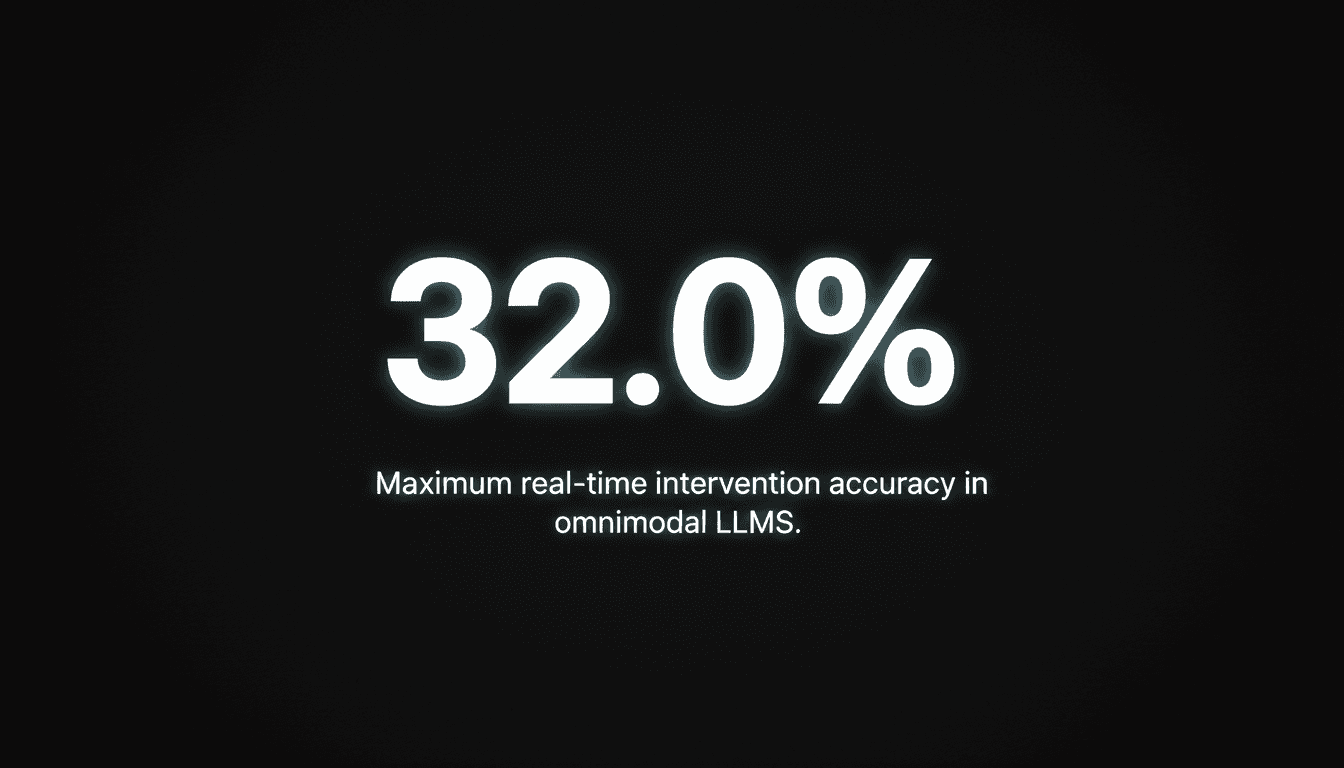
— the ceiling for joint timing-and-tool accuracy across all 12 evaluated models, demonstrating that even top-tier systems misfire or miss deadlines two-thirds of the time.
Takeaway
Expect AI developers to pivot training pipelines from offline multimodal comprehension toward continuous, event-triggered streaming architectures throughout the coming year.
Computer Vision and Pattern Recognition preprints.
"Daily stream of vision research papers and preprints."
— A47 Editor
Omni-InteractScope: Benchmarking Proactive and Agentic Interaction in Continuous Omnimodal Streams
Researchers have introduced Omni-InteractScope, a benchmark of 1,479 human-annotated, cross-reviewed interactions with 1,790 temporal targets across eight task groups, designed to test how omnimodal large language models (Omni-LLMs) respond to contin...
Machine Learning preprints from arXiv.
"Core ML theory and methods in daily preprints."
— A47 Editor
Efficient Omni-modal Large Language Model Inference via Per-Query Modality Selection
Researchers posted an arXiv cs.LG preprint, "Efficient Omni-modal Large Language Model Inference via Per-Query Modality Selection," addressing the high inference cost of omni-modal large language models (Omni-LLMs) that process text, audio, and video...
Computation and Language (NLP) preprints.
"Daily stream of NLP research papers and preprints."
— A47 Editor
Omni-UBench: Benchmarking Omni-Modal LLM-based Guardrails Across Safety, Utility, and Reliability
Researchers at arXiv (cs.CL) have introduced Omni-UBench, a benchmark framework designed to evaluate omni-modal guardrail models used with Omni-modal Large Language Models (OLLMs). The framework assesses safety, utility, and reliability across more t...