
Microsoft Releases HealthAgentBench Benchmark Exposing Performance Gaps in Frontier AI Agents for Clinical Workflows
What happened
Microsoft researchers released HealthAgentBench, a standardized benchmark evaluating frontier AI agents across 75 realistic, executable healthcare workflows.
The Context
* Replacing static evals: Previous medical AI benchmarks relied on narrow, saturated multiple-choice datasets rather than interactive, multi-step environments handling raw electronic health records and diagnostic imaging. * Rigorous multi-modal testing: The suite spans 75 tasks across nine clinical categories, evaluating frontier systems across 450 test runs on raw clinical inputs, multi-step reasoning, and binary completion criteria. * Significant imaging bottlenecks: Frontier models struggled most on complex diagnostic tasks such as CT and MRI scans, demonstrating clear boundaries where current multi-modal models fail to complete end-to-end clinical duties.
The Number
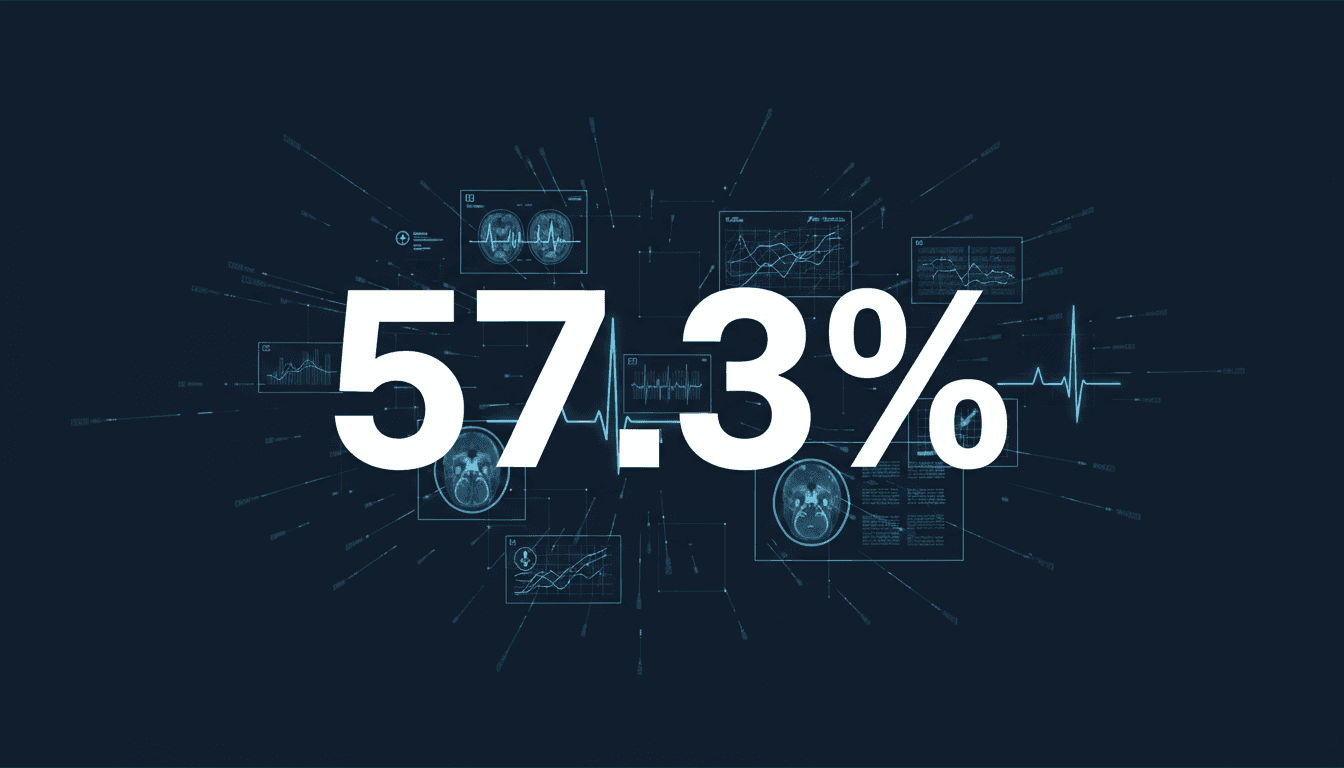
— The top overall task completion rate across the 75 clinical environments (achieved by Claude Code Opus-5.5), signaling that even leading models fail more than four out of ten complex medical workflows.
Takeaway
Expect enterprise healthcare integration to favor targeted human-in-the-loop validation over fully autonomous workflows until agents dramatically improve multi-modal execution.
Computer Vision and Pattern Recognition preprints.
"Daily stream of vision research papers and preprints."
— A47 Editor
HealthAgentBench: A Unified Benchmark Suite of Realistic Agentic Healthcare Environments for Challenging Frontier AI Agents
HealthAgentBench, a benchmark suite described in an arXiv cs.CV preprint, introduces 75 agentic healthcare tasks across 9 categories, each with its own environment. The tasks cover diagnosis, specimen assessment, research, and data management, and re...
Computation and Language (NLP) preprints.
"Daily stream of NLP research papers and preprints."
— A47 Editor
AusClinBench: a deterministically scored benchmark of large language models against current Australian clinical policy
AusClinBench, a new benchmark of 142 questions drawn from Australian clinical guidelines and schedules across PBS authority, MBS billing, Ahpra obligations, triage red flags and immunisation and screening, was used to test 28 large language models be...
Computation and Language (NLP) preprints.
"Daily stream of NLP research papers and preprints."
— A47 Editor
SCI-AGENT-EXAM: Benchmarking Agents on Scientific Research Tasks
SCI-AGENT-EXAM, a workflow-oriented benchmark published on arXiv in the cs.CL category, comprises 120 expert-curated tasks across 11 scientific fields and seven research task types defined by the Scientific Workflow Task Taxonomy. Each task requires ...