
Clip-Low and Clip-High Asymmetry Drives Opposing Entropy Effects in RLVR Training of Large Language Models
Why it matters
Understanding how objective clipping drives policy entropy collapse allows technical teams to prevent premature model determinism during post-training without altering their reward functions.
What happened (in 30 seconds)
* Researchers uncovered opposing entropy biases: A study from UCLA, Seoul National University, KRAFTON, Stanford, and Santa Clara University proves that in PPO and GRPO algorithms, clip-low increases policy entropy while clip-high decreases it. * Standard default settings accelerate collapse: Because pretrained language models exhibit heavy-head token distributions, symmetric clipping at standard settings like 0.2 allows clip-high effects to dominate, shrinking entropy regardless of the underlying reward signal. * Asymmetric clipping preserves exploration: Isolating and strengthening the clip-low threshold counters policy collapse, giving operators a direct mechanical control to sustain exploration across extended reasoning runs.
The context you actually need
* Reinforcement learning with verifiable rewards (RLVR) has become standard: Post-training workflows for complex domains like mathematics rely on verifiable feedback, but models frequently suffer from entropy collapse where responses turn rigid and deterministic. * The field historically blamed reward signals: Previous diagnostics assumed that aggressive policy collapse stemmed entirely from how rewards were shaped, overlooking the numerical constraints built directly into optimization objectives. * Clipping serves as a mathematical boundary: In Proximal Policy Optimization (PPO) and Generalized Reward Policy Optimization (GRPO), clipping limits surrogate objective updates, but its asymmetric downstream impact on probability distributions was uncharacterized until now.
What's really happening
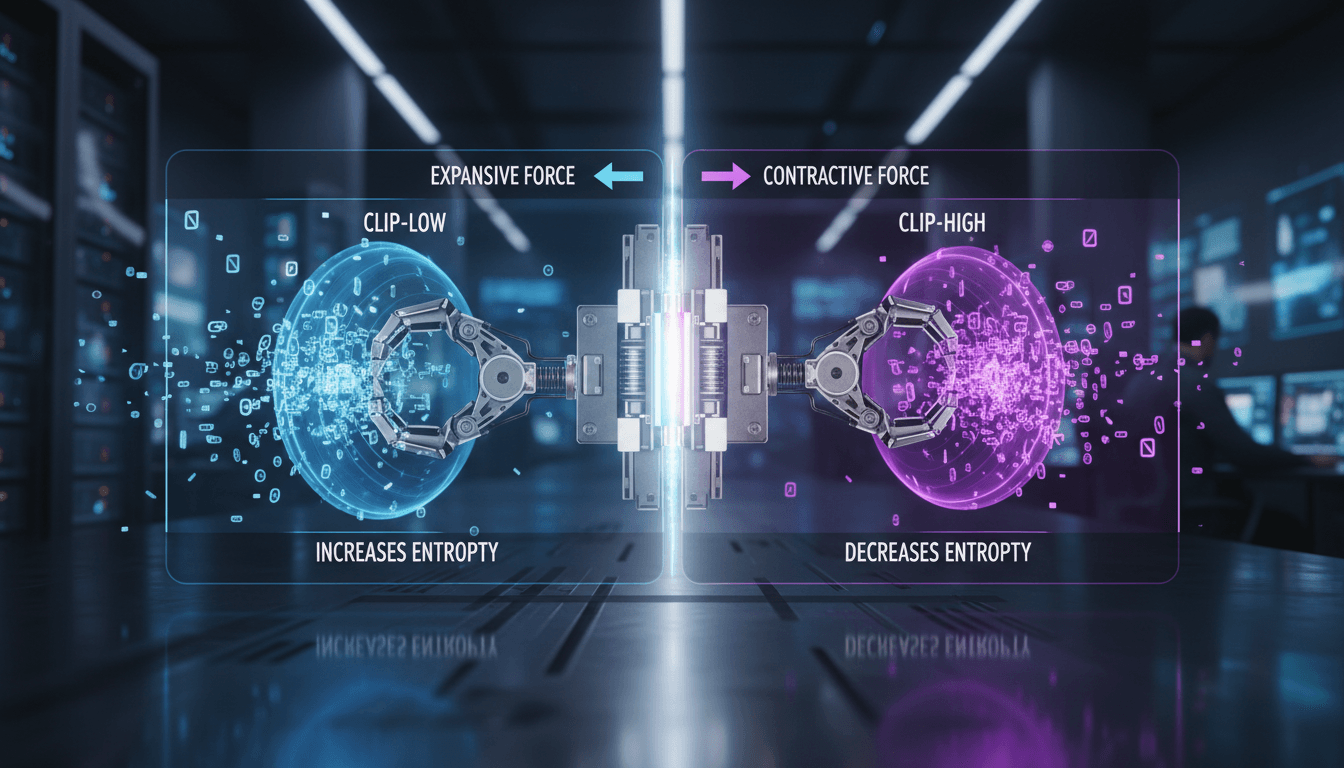
- Clip-low increases entropy: When advantage values are negative, the clip-low operator restricts updates on low-probability tokens. This restriction effectively cushions negative updates across the tail of the distribution, dispersing probability mass and increasing overall policy entropy.
- Clip-high decreases entropy: When advantage values are positive, the clip-high operator caps updates on high-probability tokens. However, because pretrained language models feature a "heavy-head" distribution—where a small subset of candidate tokens holds the overwhelming majority of probability mass—the upward pressure concentrated on these primary tokens consistently outweighs the dispersion from the tail.
Who feels it first (and how)
* LLM post-training engineers: Teams running PPO or GRPO on reasoning pipelines will need to review default symmetric hyperparameter baselines to prevent silent degradation of token exploration. * AI research labs focused on RLVR: Researchers developing math and logic models will gain a structural knob to diagnose whether training plateauing is caused by reward noise or mathematical objective clipping. * Compute infrastructure leads: Training runs that previously failed due to early entropy collapse can be stabilized by adjusting clipping ratios, reducing wasted compute cycles spent restarting collapsed runs.
What to watch next
* Asymmetric clipping hyperparameter adoption: Track whether open-source fine-tuning libraries implement separate clip-low and clip-high flags instead of a unified epsilon parameter. * Validation on broader reasoning benchmarks: Watch for follow-up empirical studies testing asymmetric clipping beyond mathematics across general code generation and multi-step agentic tasks.
Clip-low drives policy entropy up on negative advantages, clip-high drives entropy down on positive advantages, and standard symmetric clipping yields a net entropy reduction due to heavy-head token structures.
Fine-tuning teams adopting asymmetric clipping parameters will extend effective exploration timelines during long-horizon reasoning training runs.
The exact interaction between asymmetric clipping thresholds and distinct model parameter scales remains unmapped across architectures outside standard transformer decoders.
Frequently Asked Questions
- Why it matters?
- Understanding how objective clipping drives policy entropy collapse allows technical teams to prevent premature model determinism during post-training without altering their reward functions.
- What happened (in 30 seconds)?
- Researchers uncovered opposing entropy biases: A study from UCLA, Seoul National University, KRAFTON, Stanford, and Santa Clara University proves that in PPO and GRPO algorithms, clip-low increases policy entropy while clip-high decreases it. Standard default settings accelerate collapse: Because pretrained language models exhibit heavy-head token distributions, symmetric clipping at standard settings like 0.2 allows clip-high effects to dominate, shrinking entropy regardless of the underlying r
- What's really happening?
- When you run reinforcement learning on large language models, maintaining entropy is essential. Entropy represents the diversity and flexibility of your model’s token distribution. If entropy drops to near zero too early—a failure state known as entropy collapse—the model stops exploring alternative paths, fixates on repetitive token choices, and ceases learning on complex tasks like mathematical reasoning. Historically, engineers assumed that poor reward design pushed policies into this determ
- Who feels it first (and how)?
- LLM post-training engineers: Teams running PPO or GRPO on reasoning pipelines will need to review default symmetric hyperparameter baselines to prevent silent degradation of token exploration. AI research labs focused on RLVR: Researchers developing math and logic models will gain a structural knob to diagnose whether training plateauing is caused by reward noise or mathematical objective clipping. Compute infrastructure leads: Training runs that previously failed due to early entropy collapse c
- What to watch next?
- Asymmetric clipping hyperparameter adoption: Track whether open-source fine-tuning libraries implement separate clip-low and clip-high flags instead of a unified epsilon parameter. Validation on broader reasoning benchmarks: Watch for follow-up empirical studies testing asymmetric clipping beyond mathematics across general code generation and multi-step agentic tasks.
Machine Learning preprints from arXiv.
"Core ML theory and methods in daily preprints."
— A47 Editor
Clip-Low Increases Entropy and Clip-High Decreases Entropy in Reinforcement Learning of Large Language Models
Researchers posted an arXiv preprint in the cs.LG category titled "Clip-Low Increases Entropy and Clip-High Decreases Entropy in Reinforcement Learning of Large Language Models," which examines reinforcement learning with verifiable rewards (RLVR) us...
Computation and Language (NLP) preprints.
"Daily stream of NLP research papers and preprints."
— A47 Editor
Evolving Language Models without Labels: Majority Drives Selection, Novelty Promotes Variation
A new arXiv preprint in cs.CL, "Evolving Language Models without Labels: Majority Drives Selection, Novelty Promotes Variation," examines how large language models can improve without reference answers or external verifiers. It identifies a failure m...
Computation and Language (NLP) preprints.
"Daily stream of NLP research papers and preprints."
— A47 Editor
SOPO: Socratic Guided Policy Optimization for Span-Level Hallucination Detection
SOPO, a multi-turn reinforcement learning framework called Socratic Guided Policy Optimization, has been introduced on arXiv (cs.CL) to detect span-level hallucinations in Large Language Models, which often generate unfaithful or inconsistent content...