
4DMemory Preprint Introduces LongVideo Dataset and Harness for Long-Horizon Spatiotemporal Memory Evaluation in Multimodal AI
What happened
Researchers published the 4DMemory benchmark on arXiv, pairing a 900-hour video dataset with an evaluation harness that tests long-horizon spatiotemporal reasoning across 13 leading foundation models.
The Context
* Current benchmarks fall short: Standard multimodal evaluations assess brief context windows, leaving models ill-equipped to track persistent physical states or subtle environmental changes over extended timelines. * A dedicated evaluation suite: The release introduces the LongVideo dataset—spanning roughly 900 hours of footage and over 5,000 verified questions—alongside 4DMemoryBench to isolate persistent memory failures. * Tool integration bridges the gap: The accompanying 4DMemory Harness combines four specialized skills, 22 tool models, and retrieval-augmented generation to stabilize agent recall over long operational horizons.
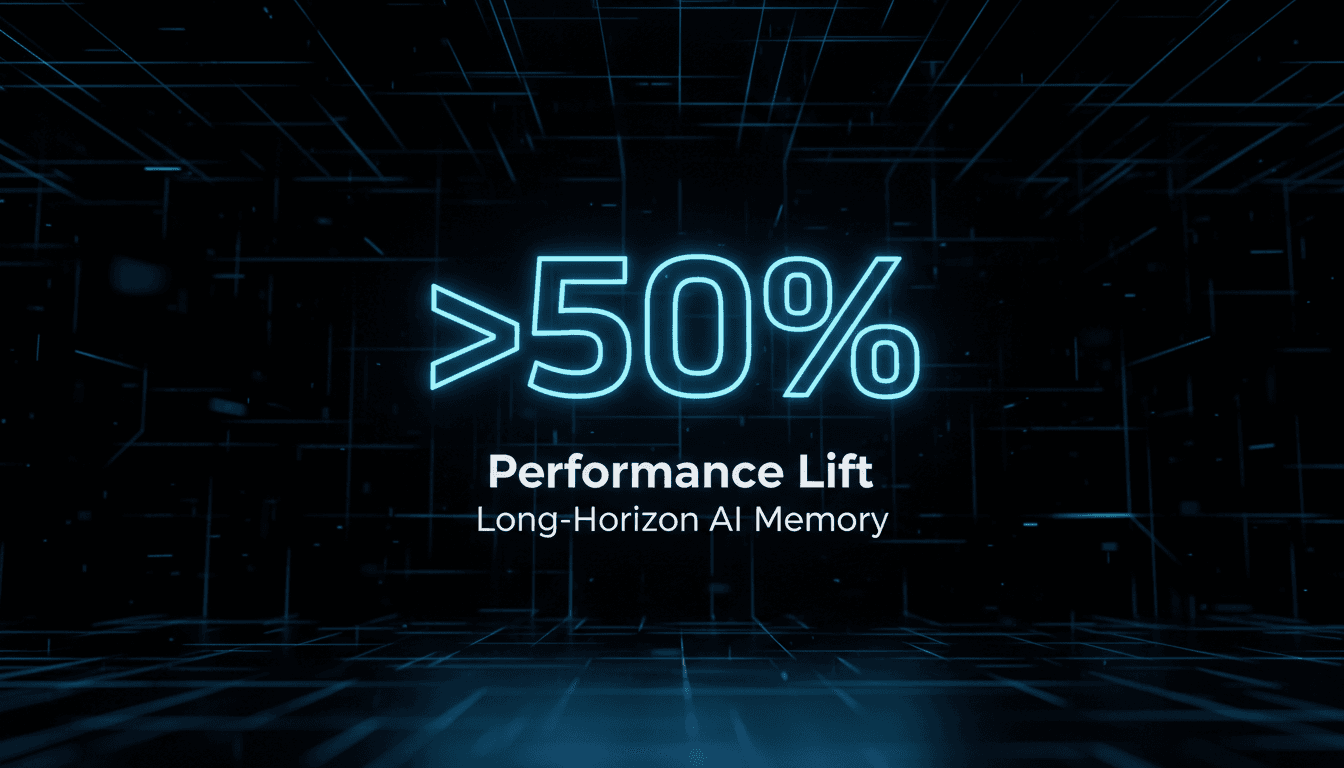
The Number
The performance boost recorded across all 13 evaluated models when equipped with the 4DMemory Harness, proving that external tool architectures outperform standalone foundation models on extended timeline recall.
Takeaway
Expect next-generation vision agents to lean heavily on external memory harnesses rather than raw parameter scaling to master multi-day enterprise workflows.
Computer Vision and Pattern Recognition preprints.
"Daily stream of vision research papers and preprints."
— A47 Editor
4DMemory: Benchmarking Long-Horizon Spatiotemporal Memory with Harness-Augmented Agents
Researchers posted an arXiv cs.CL preprint introducing 4DMemory, a benchmark for long-horizon spatiotemporal memory, alongside the LongVideo dataset of about 900 hours of video and over 5,000 manually reviewed questions. The work also presents the 4D...
Computer Vision and Pattern Recognition preprints.
"Daily stream of vision research papers and preprints."
— A47 Editor
Video-MemComp: Taylor-Guided Sensitivity-Aware Memory Management for Streaming Video Understanding
Researchers posted an arXiv cs.CV preprint introducing Video-MemComp, a training-free, sensitivity-aware context management framework designed to ease memory bottlenecks in Multimodal Large Language Models (MLLMs) when processing long, streaming vide...
Computer Vision and Pattern Recognition preprints.
"Daily stream of vision research papers and preprints."
— A47 Editor
SpatialMem: Metric-Aligned Long-Horizon Video Memory for Language Grounding and QA
SpatialMem is a memory-based system that combines 3D geometry, semantics, and language into one queryable representation, built from casually recorded egocentric RGB video. It reconstructs metrically scaled interior scenes, identifies structural anch...